
AI Engineering & Intelligent Systems
We build production AI systems designed for actual enterprise workflows, not fragile demos. From high-throughput vector retrieval and cognitive agent orchestration to custom model fine-tuning and inference pipelines, we engineer reliable intelligence directly into your core product architecture.
Building interfaces that people love to use.
Strategic AI Architecture & Integration
AI engineering at EPIOSO is driven by verifiable performance, not speculative experiments. We transform frontier foundation models and custom architectures into resilient production systems: low-latency agent loops, zero-hallucination knowledge retrieval, autonomous document pipelines, and clinical-grade decision support.
Core Deliverables & Capabilities
- Production RAG & Knowledge Retrieval
Hybrid search architectures, dynamic reranking, and semantic vector stores engineered for deterministic accuracy and zero hallucination over massive proprietary datasets.
- Autonomous Cognitive Agents
Multi-agent orchestration frameworks equipped with state persistence, structured function calling, and strict human-in-the-loop controls for complex operations.
- Custom Model Alignment & Inference
Domain-specific fine-tuning (LoRA/QLoRA), specialized embeddings, and optimized inference serving built for predictable throughput and low latency.
AI Engineering Methodology
Domain Framing & Model Selection
/001We formalize system boundaries, evaluation benchmarks, and latency targets before selecting proprietary models or open weights.
Vector Architecture & Context Design
/002We structure semantic chunking strategies, dense-sparse embedding pipelines, and deterministic metadata filters for hybrid retrieval.
Agent Orchestration & Deterministic Controls
/003We implement function calling contracts, state machines, structured JSON outputs, and strict guardrails to prevent hallucinations.
Benchmarking, Evals & Hardening
/004We stress-test pipelines against synthetic failure datasets, optimize token economics, and establish automated LLM-as-a-judge evals.

- Optimized End-to-End Inference Latency
- <1.2s
- Tolerance for Unvalidated Hallucinations
- Zero
- Autonomous Agents with Deterministic Safeguards
- Production
Ready to start?
Let's build something great together.
Integrated Capabilities & Downstream Solutions
Business Automation & AI Workflows
Orchestrate autonomous agent loops, intelligent document parsing, and event-driven automation pipelines directly into your operational toolstack.
Healthcare Technology & Digital Health
Deploy clinical-grade AI diagnostics, secure triage decision-support models, and HIPAA/GDPR-compliant health data architectures.
Other Services
Branding & Digital Identity
Strategic visual identities and design systems built to make growing businesses look authoritative.
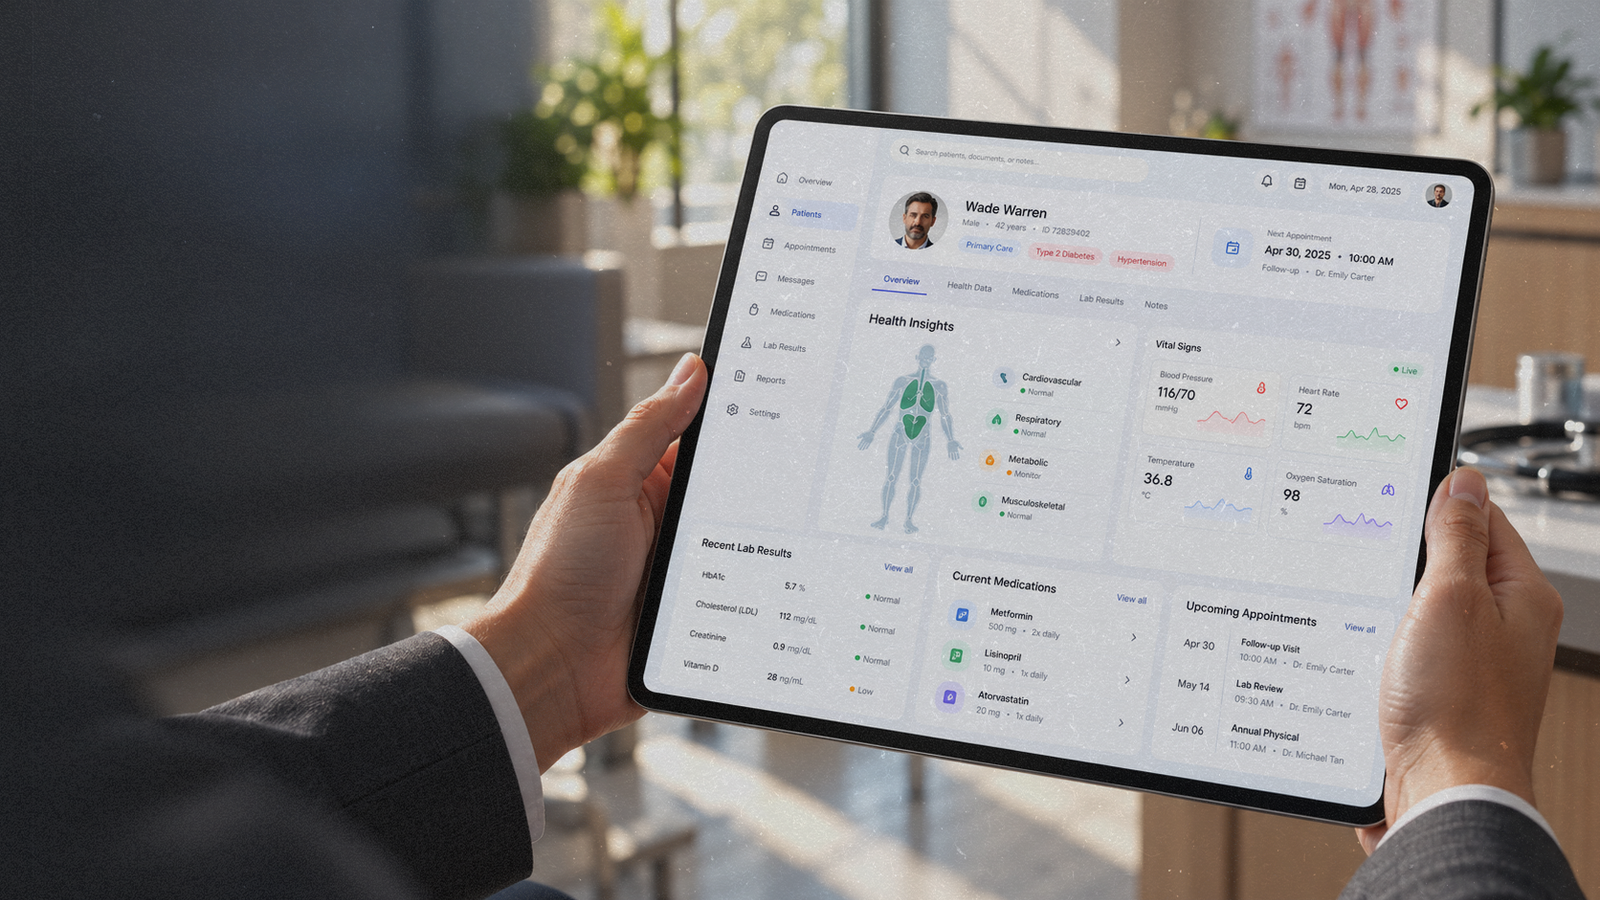
Healthcare Technology & Digital Health
Clinical-grade software, secure patient platforms, and medical AI systems engineered with deep biomedical informatics expertise.
Systems & Backend Engineering
Resilient distributed systems, mission-critical APIs, and high-concurrency database architectures designed to scale effortlessly.
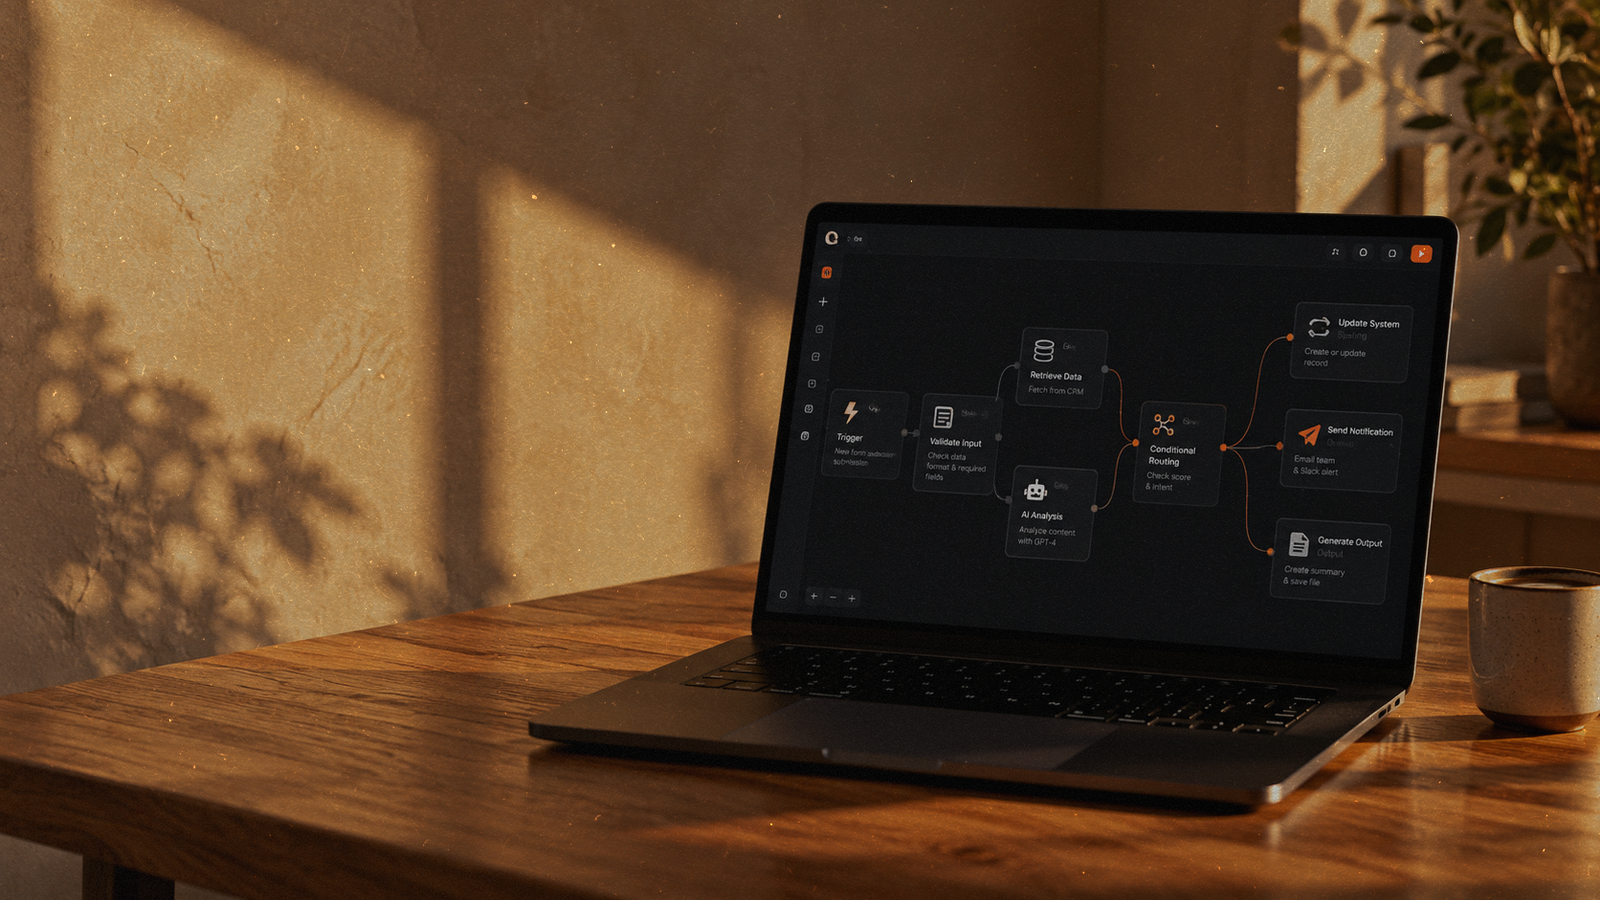
Business Automation & AI Workflows
End-to-end workflow automation, autonomous AI agents, and cross-platform integrations designed to eliminate operational friction at scale.
What's your business called?
We reply within 24 hours.